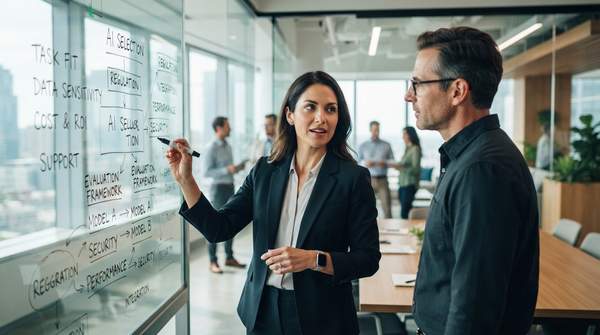
For a consulting, legal, or research firm, the question is no longer whether to adopt a large language model—it is which type to adopt. The honest answer is that no single model wins on every dimension, and headline benchmark scores are a poor proxy for business fit. What matters is a structured evaluation across four dimensions: the tasks you actually perform, how sensitive your client data is, how each cost model behaves at your workload, and how much support your team can rely on. This article walks through that evaluation and ends with a decision framework your firm can apply directly.
Understanding AI Model Categories: Proprietary vs. Open-Source
Every LLM a firm can adopt falls into one of two broad categories, and the distinction drives almost everything else. Proprietary models are accessed through a provider's API or subscription: you pay a recurring fee, the provider hosts the model, and updates arrive on the provider's schedule. Alfons Futterer, writing for NanoMatrix Secure, notes that most proprietary providers offer free trials, professional onboarding support, deployment engineers, and regular updates—conveniences that come bundled with the subscription or usage fee.
Open-source (or open-weight) models invert that arrangement. The software itself is often free or low cost, but the firm takes on deployment, hardware, and maintenance. Futterer's comparison is blunt on this point: deployment costs for open-source models run very high compared to proprietary ones. What you buy with that investment is control—over where data lives, how the model is configured, and what it is optimized for.
The market context makes this trade-off timely. An analysis from the Center for Strategic and International Studies observes that leading U.S. closed-source models remain expensive for many developers and enterprises, while open-weight alternatives offer a cheaper option—and as the capability gap between the two narrows, price differences are likely to push even U.S. enterprises toward open-weight models. In other words, the choice is becoming genuinely competitive rather than a lopsided convenience-versus-cost calculation.
Key Evaluation Dimensions for Professional Services Firms
Four dimensions should anchor any selection process, and each carries a distinct trade-off.
Task type. Different professional tasks demand different model strengths. A widely cited business comparison maps this directly: basic text drafting needs speed and creativity, so lightweight, fast models suffice; complex data analysis needs logic and a large context window, pointing to advanced reasoning models; internal knowledge search depends on broad context windows and retrieval support; and customer support bots require low latency above all. Matching the model profile to the task prevents both overspending on capability you don't use and underbuying for work that demands reasoning depth.
Data security. For firms handling privileged or confidential client material, this dimension can be decisive. The biggest security factor, as that same business comparison frames it, is data containment: you must know whether your prompts train the provider's public model. Consumer-grade chat tools often use your input to train their next version, which means private client data could surface in answers given to other people. Business-grade API connections usually prevent this—but the terms of service must be read closely, and the provider's commitments verified rather than assumed.
Cost model. Proprietary pricing scales with usage, typically through subscription tiers and per-token fees. Damon Garn, reviewing AI chatbot pricing for TechTarget, cautions that while pricing is remarkably similar across many vendors, tiered systems with access restrictions and performance benefits can affect cost effectiveness—so each vendor's tiers should be evaluated to confirm you can get needed features at a reasonable price. Open-source pricing, by contrast, is front-loaded: hardware, deployment, and ongoing maintenance.
Support and maintenance. Proprietary providers generally include professional support and regular updates; open-source relies on community-based support, which Futterer notes may be irregular, or on your own in-house technical team.
Aligning AI Models with Specific Business Tasks
Once the dimensions are clear, the next step is to inventory your firm's actual work. A litigation practice summarizing discovery documents, a consultancy analyzing client datasets, and a research firm building an internal knowledge base have different bottlenecks. The task-to-strength mapping above is the practical filter: a firm whose primary workload is drafting and summarization does not need to pay reasoning-model premiums, while a firm doing complex analysis should not economize on capability.
Two cautions apply. First, performance varies by model even within a category, so any task-to-model mapping is a starting hypothesis, not a conclusion—it requires testing on your own work. Second, the user experience matters as much as raw capability. Garn's advice is to evaluate the tool from the user's perspective: the best option isn't just technically capable, it needs to feel approachable and intuitive, because a good interface and effective APIs go a long way toward getting employees comfortable using AI tools. Adoption fails at the interface, not the benchmark.
Building an Internal AI Model Evaluation ('Eval') Process
The single most valuable step a firm can take is to stop trusting marketing claims and start testing shortlisted models against its own work. The business comparison guidance is concrete: run the comparison by testing engines against real business data, measuring speed, cost, and output quality—never relying on marketing claims alone.
The process starts simply: gather at least three real examples of work your team currently does manually. These should represent your production workload, not idealized samples. Include both routine cases and genuinely difficult ones, because models that look equivalent on easy inputs often diverge sharply on hard ones. Strip out sensitive client information before anything touches an external provider—this protects confidentiality and keeps your eval consistent with your own data containment requirements.
Then define a scoring standard before you run anything. Decide in advance what a good output looks like: accuracy thresholds, acceptable error types, required formatting, and the latency your workflow tolerates. Score each model against the same rubric on the same inputs. This converts an impressionistic "it feels smart" into a comparable, documented result—and it produces evidence you can show partners or clients when justifying the choice.
AI Model Selection Framework for Professional Services
The matrix below weighs the two model categories against the four evaluation dimensions. Read it against your own requirements: high data sensitivity pushes toward the open-source column; limited in-house technical capacity pushes toward the proprietary column.
| Dimension | Proprietary (API-based) | Open-Source (deployment-based) |
|---|---|---|
| Task type | Suitable for a range of tasks, including complex data analysis and customer support, depending on the specific model's capabilities. Performance varies by model; requires testing for specific tasks. | Can be optimized for specific tasks like internal knowledge search or basic drafting, with flexibility for customization. Requires in-house expertise for deployment and fine-tuning. |
| Data security | Data handling depends on the provider's policies; typically a managed environment. Firms must verify the provider's data privacy and security commitments. | Greater control over data containment since models are hosted internally. Security depends on the firm's own infrastructure and practices. |
| Cost model | Subscription fees plus usage-based (per-token) costs. Costs can scale with usage, requiring careful monitoring. | Initial deployment, hardware, and ongoing maintenance costs. Requires significant upfront investment and technical resources. |
| Support and maintenance | Often includes professional support and regular updates from the provider. Level of support varies by service tier. | Relies on community-based support or in-house technical teams. Support availability and quality can be less predictable than proprietary options. |
Use the matrix as a weighing exercise rather than a scorecard. A firm with strict client-confidentiality obligations and existing infrastructure may accept open-source deployment costs in exchange for total data governance. A firm without a technical team, running variable workloads, may find that predictable subscription tiers and vendor support are worth the per-token spend. Most firms will land on a primary category first, then shortlist specific models within it.
Strategic Decision: Choosing Your AI Model Category
Professional services firms should select an AI model category (proprietary or open-source) based on a structured evaluation of their specific task requirements, data security needs, total cost of ownership, and desired support level, rather than solely on advertised performance benchmarks. The category decision comes first because it determines your cost structure, your security posture, and your staffing needs before any specific model is even shortlisted.
The measurable indicator of success is straightforward: the firm has a documented internal rubric for evaluating AI models, and a shortlist of models has been identified for in-house 'eval' testing. Until those two artifacts exist, the selection process is still opinion; once they exist, it is evidence. From there, the next milestone is running the shortlisted models against your real workload samples and comparing their scores on speed, cost, and output quality against the rubric you defined.
Sources
- AI Models: Choosing the Right Type For Your Business — NanoMatrix Secure
- What to Know About Chinese AI Models — CSIS
- AI Model Comparison: Which LLM Fits Your Business? — LaunchLemonade
- The best AI chatbots for 2026: Compare features and costs — TechTarget